Project Glasswing: AI Finds Bugs Faster Than Humans Can Fix Them
Imagine you maintain an open-source library used by millions. One morning, your inbox gains 45 new vulnerability reports — all sent by an AI scanner, with no human review. This is not a hypothetical: it is exactly what Daniel Stenberg, the maintainer of curl, just went through with Anthropic’s Project Glasswing. After seven months, Project Glasswing has found 37,966 vulnerabilities — but only 217 have been fixed. The bottleneck has moved from discovery to remediation, and this article shows how to read the numbers right, plus a checklist for handling AI reports.
What Is Project Glasswing?
Project Glasswing is Anthropic’s coordinated vulnerability research initiative, launched on April 7, 2026. Its main tool is Claude Mythos Preview — a model built for finding security bugs, not publicly released. The stated goal at launch: find thousands of high- and critical-severity vulnerabilities and responsibly disclose them to open-source maintainers.
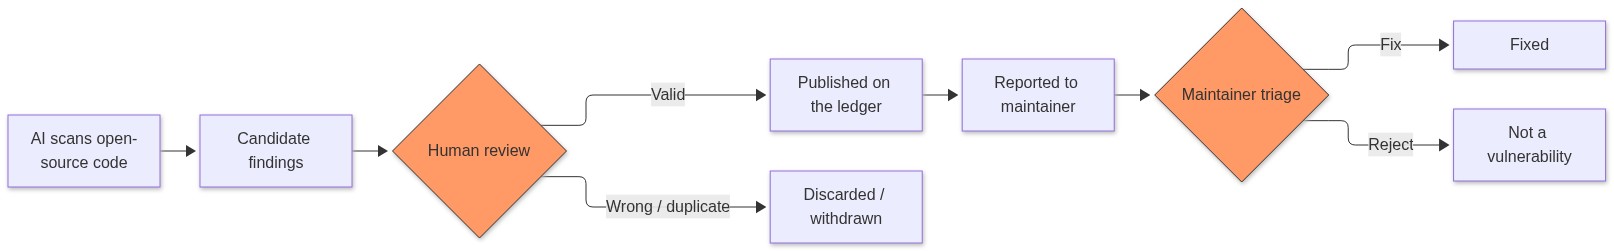
The pipeline has five steps: AI scans open-source code and produces candidate findings; Anthropic’s team manually reviews each finding; validated findings go public on the ledger (red.anthropic.com); Anthropic reports them to the relevant maintainer; finally, the maintainer verifies and fixes the bug. The two middle steps — manual review and fixing — run at human speed, and that is where everything stalls.
In May 2026, when the ledger first went public, Anthropic reported 23,019 findings with a 90.8% true-positive rate — but “findings” is not the same as “confirmed vulnerabilities”.
Read the Numbers Right: 37,966 Is Not 37,966 Bugs
The most common mistake when reading AI bug-hunt news is treating every number as equal. In reality, a finding passes through four layers before it becomes a fixed bug: candidate, made public, reported to a maintainer, and finally fixed.
As of the ledger update on November 2, 2026, Project Glasswing reported 37,966 findings. Only 7,349 (19.4%) were made public, and only 217 were marked fixed — 0.57% of all findings, or 2.9% of the public ones. One in every 175 findings found by the AI has actually been fixed.
The 94.2% true-positive rate on the ledger needs a question mark next to it. It is Anthropic’s own claim, and VulnCheck — which has tracked the project independently since April — publicly doubts how it is calculated: findings marked duplicate (1,670) and withdrawn (419) add up to 2,089, nearly 10 times the number fixed (217). If the true-positive rate were really 94.2%, the number of discarded findings could not be many times larger than the number fixed — the ledger may be missing a feedback loop that subtracts duplicates and withdrawals from the rate.
Severity ratings diverge too: in September’s analysis, Claude rated 91.5% of ledger findings critical or high, while maintainers rated only 51.3% that way. Automated severity is not reliable enough to set priorities. VulnCheck also found a bug on Anthropic’s own ledger that inflates the number of findings marked “disclosed” — anyone can check with the “disclosed” filter on the ledger.
The same counting trap appeared in our GPT-6 Cyber found 948 Linux kernel bugs article: 948 was the number of candidate patches the model produced, not 948 patched CVEs. Counting findings without counting fixes always makes the picture look better than it is.
Results After 7 Months: The Numbers, Sep 8 vs Nov 2
| Metric | Sep 8, 2026 | Nov 2, 2026 | Change |
|---|---|---|---|
| Total findings | 26,153 | 37,966 | +11,813 |
| Made public | 2,736 (10.5%) | 7,349 (19.4%) | +4,613 |
| Fixed | 202 | 217 | +15 |
| Withdrawn | 245 | 419 | +174 |
| Duplicates | 2 | 1,670 | +1,668 |
| Claimed true-positive rate (Anthropic) | 91.4% | 94.2% | +2.8 pts |
Source: Anthropic’s public ledger, updated Nov 2, 2026, via VulnCheck’s analysis (November 2026).
Read the table row by row and the problem is plain: in eight weeks, findings grew by 11,813 (up 45%), but fixes grew by only 15. Duplicates went from 2 to 1,670 — VulnCheck warned in September that the longer findings sit, the more likely someone else finds and fixes them first.
VulnCheck also counts CVEs independently. After seven months, it tracked 442 CVEs attributable to Anthropic — about 0.5% of all CVEs published in 2026 (93,450). Of those, only 2 were exploited in the wild (CVE-2026-61500 and CVE-2026-26980), or 0.45%. AI is very good at finding bugs, but most of the bugs it finds have never been touched by an attacker — and have not been fixed either.
OSS Scanner: The Bottleneck Moves to Maintainers
On October 8, 2026, Anthropic launched OSS Scanner — an open-source scanning tool that projects opt into on GitHub, where maintainers request scans and triage the results themselves. Anthropic states plainly in the launch post that these reports are “fully model-generated, without human review or triage” and “may be incorrect or invalid”.
Anthropic also openly admitted the reason for OSS Scanner: it is “bottlenecked on our human capacity to validate these findings”. By then, Project Glasswing had found over 29,000 candidate findings but the team had manually reviewed only about 6,000, and it had already sent nearly 5,000 unverified reports to maintainers who asked for everything in bulk. The validation bottleneck did not disappear — it moved from Anthropic to the maintainers.
The curl case shows the cost of that move. Daniel Stenberg received a batch of 45 reports from Anthropic, only one of them rated medium, the rest low. He had to move each report to GitHub in a controlled way “to soften the impact for the team”. At the time of VulnCheck’s analysis, of the 34 reports published so far: 19 were marked not a vulnerability, 6 confirmed as low severity, 9 awaiting assessment. The false-positive rate so far was 55.9%, and only 17.6% of findings were confirmed — all of them low severity. Back in May, five Mythos findings sent to curl boiled down to a single real vulnerability.
The lesson is not “don’t use AI to scan”. NVIDIA’s SkillSpector follows the same principle: automated scanning is only valuable with an independent verification loop — scan AI skills before installing, score the risk 0–100, then a human decides. With vulnerability reports, the logic is the same: AI finds, humans verify, then act.
Checklist: How Maintainers and Security Teams Handle AI Reports
When your inbox starts receiving AI-generated reports, don’t treat them like reports from a traditional security researcher. This process works for both open-source maintainers and enterprise security teams.
1. Prioritize by exploitability, not by AI-assigned severity. A “critical” finding from Claude with no real exploitation path ranks below a “medium” finding that already has a PoC.
2. Ask for minimum evidence before deep verification. A report with no PoC, no clear trigger conditions, or no specific lines of code goes back with a “needs-info” label.
3. Check for duplicates before opening a new ticket. Search VulnCheck’s public tracker, which collects every Anthropic-attributed CVE, to see whether the finding has already been reported or fixed:
git clone --depth 1 https://github.com/patrickmgarrity/Anthropic-Credited-CVEs4. Triage in public, transparently. Follow curl’s example: publish each report as an issue with a clear triage result. Transparency helps other projects avoid duplicate verification.
5. Set intake rules for AI reports. Accept reports only through a designated channel, refuse unverified bulk reports, and set a response SLA — for example, acknowledging receipt within 5 working days.
6. For enterprise security teams: match against your own inventory first. A finding only deserves priority if it touches a dependency actually running in your systems. Match findings against your SBOM before queuing them.
7. Don’t patch automatically from AI reports. A candidate patch needs review like any other pull request. Shannon — an AI pentester for web apps and APIs — works on the same principle: AI proposes, humans verify, then fix.
8. Track the false-positive rate of each source. Record the confirmed/not-a-vulnerability ratio per scanner over time. A source with a persistently high false-positive rate gets a lower triage priority.
Gotchas: Common Mistakes When Reading AI Bug-Hunt News
Trusting the findings count blindly. 37,966 is the number of candidates the AI produced, not confirmed bugs. The number that matters is 217 fixed.
Confusing “reported” with “fixed”. A finding published on the ledger or sent to a maintainer does not mean it has been patched — only 2.9% of public findings are marked fixed.
Trusting a vendor’s true-positive rate without an independent sample. The ledger says 94.2%, but the curl sample shows a 55.9% false-positive rate. In my view, when a vendor grades its own work, that number is a starting point for checking, not a conclusion.
Trusting AI-assigned severity. Claude rated 91.5% of findings critical/high; maintainers agreed on 51.3%. Severity is an opinion, not a fact — and the AI’s opinion still needs calibration.
Ignoring duplicates and withdrawals. 1,670 duplicates and 419 withdrawals together are nearly 10 times the number fixed. A program where discards grow faster than fixes has a problem in its input validation, not in its patching.
Confusing “public” with “dangerous”. Only 2 of 442 Anthropic-attributed CVEs were exploited in the wild. Most bugs the AI finds have never been touched by an attacker — not every finding is an emergency.
Conclusion
- AI has won at discovery — 37,966 findings in seven months — but verification and patching still run at human speed, and that is the real bottleneck.
- Don’t judge a bug-finding program by its findings count; count the fixes, the duplicates, and the false-positive rate from an independent sample.
- Maintainers and security teams need clear intake rules for AI reports: ask for a PoC, check for duplicates, and publish triage results.
Lessons learned
- Count fixes, not findings: 217 out of 37,966 (0.57%) is the real measure of Project Glasswing after seven months.
- Every vendor-reported true-positive rate needs an independent sample: curl showed a 55.9% false-positive rate while the ledger claimed 94.2%.
- AI-assigned severity needs calibration: 91.5% critical/high according to Claude, 51.3% according to maintainers — don’t prioritize by this number.
- Unverified bulk reports create a real burden: 45 reports forced curl’s maintainer to publish them in batches to protect his team.
- Duplicates grow over time: findings left sitting are more likely to be found and fixed by someone else first — from 2 to 1,670 in eight weeks.
- Public transparency helps the whole ecosystem: curl’s approach of publishing each report is recommended by VulnCheck, because it reduces duplicate verification and gives the community a real sample to check against.
Verification scope
Checked on November 11, 2026. The key figures in this article — 37,966 findings, 7,349 public, 217 fixed, the Sep 8 vs Nov 2 table, 442 CVEs, 2 exploited CVEs, and the curl case with 45 reports — were cross-checked directly against VulnCheck’s analysis (November 2026) and Anthropic’s public ledger (updated Nov 2, 2026). Anthropic’s ledger is a JavaScript-rendered web app, so the figures were cross-checked through VulnCheck’s analysis and an independent audit on DEV.to, both citing the same ledger. The 94.2% true-positive rate is Anthropic’s claim, currently disputed by VulnCheck — this article states that clearly. Supplementary figures from Anthropic’s dashboard (29,439 candidates, 516 patched) were not used because they could not be verified directly. The author did not run Project Glasswing or OSS Scanner; all assessments of the process are based on public documentation and independent analysis, not hands-on experience.
Bình luận
Bình luận được duyệt trước khi hiển thị.Đang tải bình luận…
Để lại bình luận